Category Archives: AI

Data for Policy: Ten takeaways from the conference

The knowledge and thinking on changing technology, the understanding of the computing experts and those familiar with data, must not stay within conference rooms and paywalls.

What role do data and policy play in a world of post-truth politics and press? How will young people become better informed for their future?

The data for policy conference this week, brought together some of the leading names in academia and a range of technologists, government representatives, people from the European Commission, and other global organisations, Think Tanks, civil society groups, companies, and individuals interested in data and statistics. Beyond the UK, speakers came from several other countries in Europe, from the US, South America and Australia.

The schedule was ambitious and wide-ranging in topics. There was brilliant thinking and applications of ideas. Theoretical and methodological discussions were outnumbered by the presentations that included practical applications or work in real-life scenarios using social science data, humanitarian data, urban planning, public population-wide administrative data from health, finance, documenting sexual violence and more. This was good.

We heard about lots of opportunities and applied projects where large datasets are being used to improve the world. But while I always come away from these events having learned something and encouraged to learn more about those I didn’t, I do wonder if the biggest challenges in data and policy aren’t still the simplest.

No matter how much information we have, we must use it wisely. I’ve captured ten takeaways of things I would like to see follow. This may not have been the forum for it.

Ten takeaways on Data-for-Policy

1. Getting beyond the Bubble

All this knowledge must reach beyond the bubble of academia, beyond a select few white-male-experts-in well off parts of the world, and get into the hands and heads of the many. Ways to do this must include reducing the cost or changing  pathways of academic print access. Event and conference fees are also a  barrier to many.

2. Context of accessibility and control

There is little discussion of the importance of context. The nuance of most of these subjects was too much for the length of the sessions but I didn’t hear any single session mention threats to data access and trust in data collection posed by surveillance or state censorship or restriction of access to data or information systems, or the editorial control of knowledge and news by Facebook and co. There was no discussion of the influence of machine manipulators, how bots change news or numbers and create fictitious followings.

Policy makers and public are influenced by the media, post-truth or not. Policy makers in the UK government recently wrote in response to challenge over a Statutory Instrument that if Mums-net wasn’t kicking up  a fuss then they believed the majority of the public were happy. How are policy makers being influenced by press or social media statistics without oversight or regulating for their accuracy?

Increasing data and technology literacy in policy makers, is going to go far beyond improving an understanding of data science.

3. Them and Us

I feel a growing disconnect between those ‘in the know’ and those in ‘the public’. Perhaps that is a side-effect of my own understanding growing about how policy is made, but it goes wider. Those who talked about ‘the public’ did so without mention that attendees are all part of that public. Big data, are often our data. We are the public.

Vast parts of the population feel left behind already by policy and government decision-making; divided by income, Internet access, housing, life opportunites, and the ability to realise our dreams.

How policy makers address this gulf in the short and long term both matter as a foundation for what data infrastructure we have access to, how well trusted it is, whose data are included and who is left out of access to the information or decision-making using it.

Researchers prevented from accessing data held by government departments, perhaps who fear it will be used to criticise rather than help improve policy of the day, may be limiting our true picture of some of this divide and its solutions.

Equally data that is used to implement top-down policy without public involvement, seems a shame to ignore public opinion. I would like to have asked, does GDS in its land survey work searching for free school sites include people surveys asking, do you want a free school in your area at all?

4. There is no neutral

Global trust in politics is in tatters. Trust in the media is as bad. Neither appear to be interested across the world in doing much to restore their integrity.

All the wisdom in the world could not convince a majority in the 23rd June referendum, that the UK should remain in the European Union. This unspoken context was perhaps an aside to most of the subjects of the conference which went beyond the UK,  but we cannot ignore that the UK is deep in political crisis in the world, and at home the Opposition seems to have gone into a tailspin.

What role do data and evidence have in post-truth politics?

It was clear in discussion, that if I mentioned technology and policy in a political context, eyes started to glaze over. Politics should not interfere with the public interest, but it does and cannot be ignored. In fact it is short term political terms and needs for long term vision that are perhaps most at-odds in making good data policy plans.

The concept of public good, is not uncomplicated. It is made more complex still if you factor in changes over time, and cannot ignore that Trump or Turkey are not fictitious backdrops considering who decides what the public good and policy priorities should be.

Researchers’ role in shaping public good is not only about being ethical in their own research, but having the vision to have safeguards in place for how the knowledge they create are used.

5. Ethics is our problem, but who has the solution?

While many speakers touched on the common themes of ethics and privacy in data collection and analytics, saying this is going to be one of our greatest challenges, few address how, and who is taking responsibility and accountability for making it happen in ways that are not left to big business and profit making decision-takers.

It appears from last year, that ethics played a more central role. A year later we now have two new ethical bodies in the UK, at the UK Statistics Authority and at the Turing Institute. How they will influence the wider ethics issues in data science remains to be seen.

Legislation and policy are not keeping pace with the purchasing power or potential of the big players, the Googles and Amazons and Microsofts, and a government that sees anything resulting in economic growth as good, is unlikely to be willing to regulate it.

How technology can be used and how it should be used still seems a far off debate that no one is willing to take on and hold policy makers to account for. Implementing legislation and policy underpinned with ethics must serve as a framework for giving individuals insight into how decisions about them were reached by machines, or the imbalance of power that commercial companies and state agencies have in our lives that comes from insights through privacy invasion.

6. Inclusion and bias

Clearly this is one event in a world of many events that address similar themes, but I do hope that the unequal balance in representation across the many diverse aspects of being human are being addressed elsewhere.  A wider audience must be inclusive. The talk by Jim Waldo on retaining data accuracy while preserving privacy was interesting as it showed how deidentified data can create bias in results if data is very different from the original. Gaps in data, especially using big population data which excludes certain communities, wasn’t something I heard discussed as much.

7.Commercial data sources

Government and governmental organisations appear to be starting to give significant weight to the use of commercial data and social media data sources. I guess any data seen as ‘freely available’ that can be mined seems valuable. I wonder however how this will shape the picture of our populations, with what measures of validity and  whether data are comparable and offer reproducability.

These questions will matter in shaping policy and what governments know about the public. And equally, they must consider those communities whether in the UK or in other countries, that are not represented in these datasets and how these bias decision-making.

8. Data is not a panacea for policy making

Overall my take away is the important role that data scientists have to remind policy makers that data is only information. Nothing new. We may be able to access different sources of data in different ways, and process it faster or differently from the past, but we cannot rely on data of itself to solve the universal problems of the human condition. Data must be of good integrity to be useful and valuable. Data must be only one part of the library of resources to be used in planning policy. The limitations of data must also be understood. The uncertainties and unknowns can be just as important as evidence.

9. Trust and transparency

Regulation and oversight matter but cannot be the only solutions offered to concerns about shaping what is possible to do versus what should be done. Talking about protecting trust is not enough. Organisations must become more trustworthy if trust levels are to change; through better privacy policies, through secure data portability and rights to revoke consent and delete outdated data.

10. Young people and involvement in their future

What inspired me most were the younger attendees presenting posters, especially the PhD student using data to provide evidence of sexual violence in El Salvador and their passion for improving lives.

We are still not talking about how to protect and promote privacy in the Internet of Things, where sensors on every street corner in Smart Cities gather data about where we have been, what we buy and who we are with. Even our children’s toys send data to others.

I’m still as determined to convince policy makers that young people’s data privacy and digital self-awareness must be prioritised.

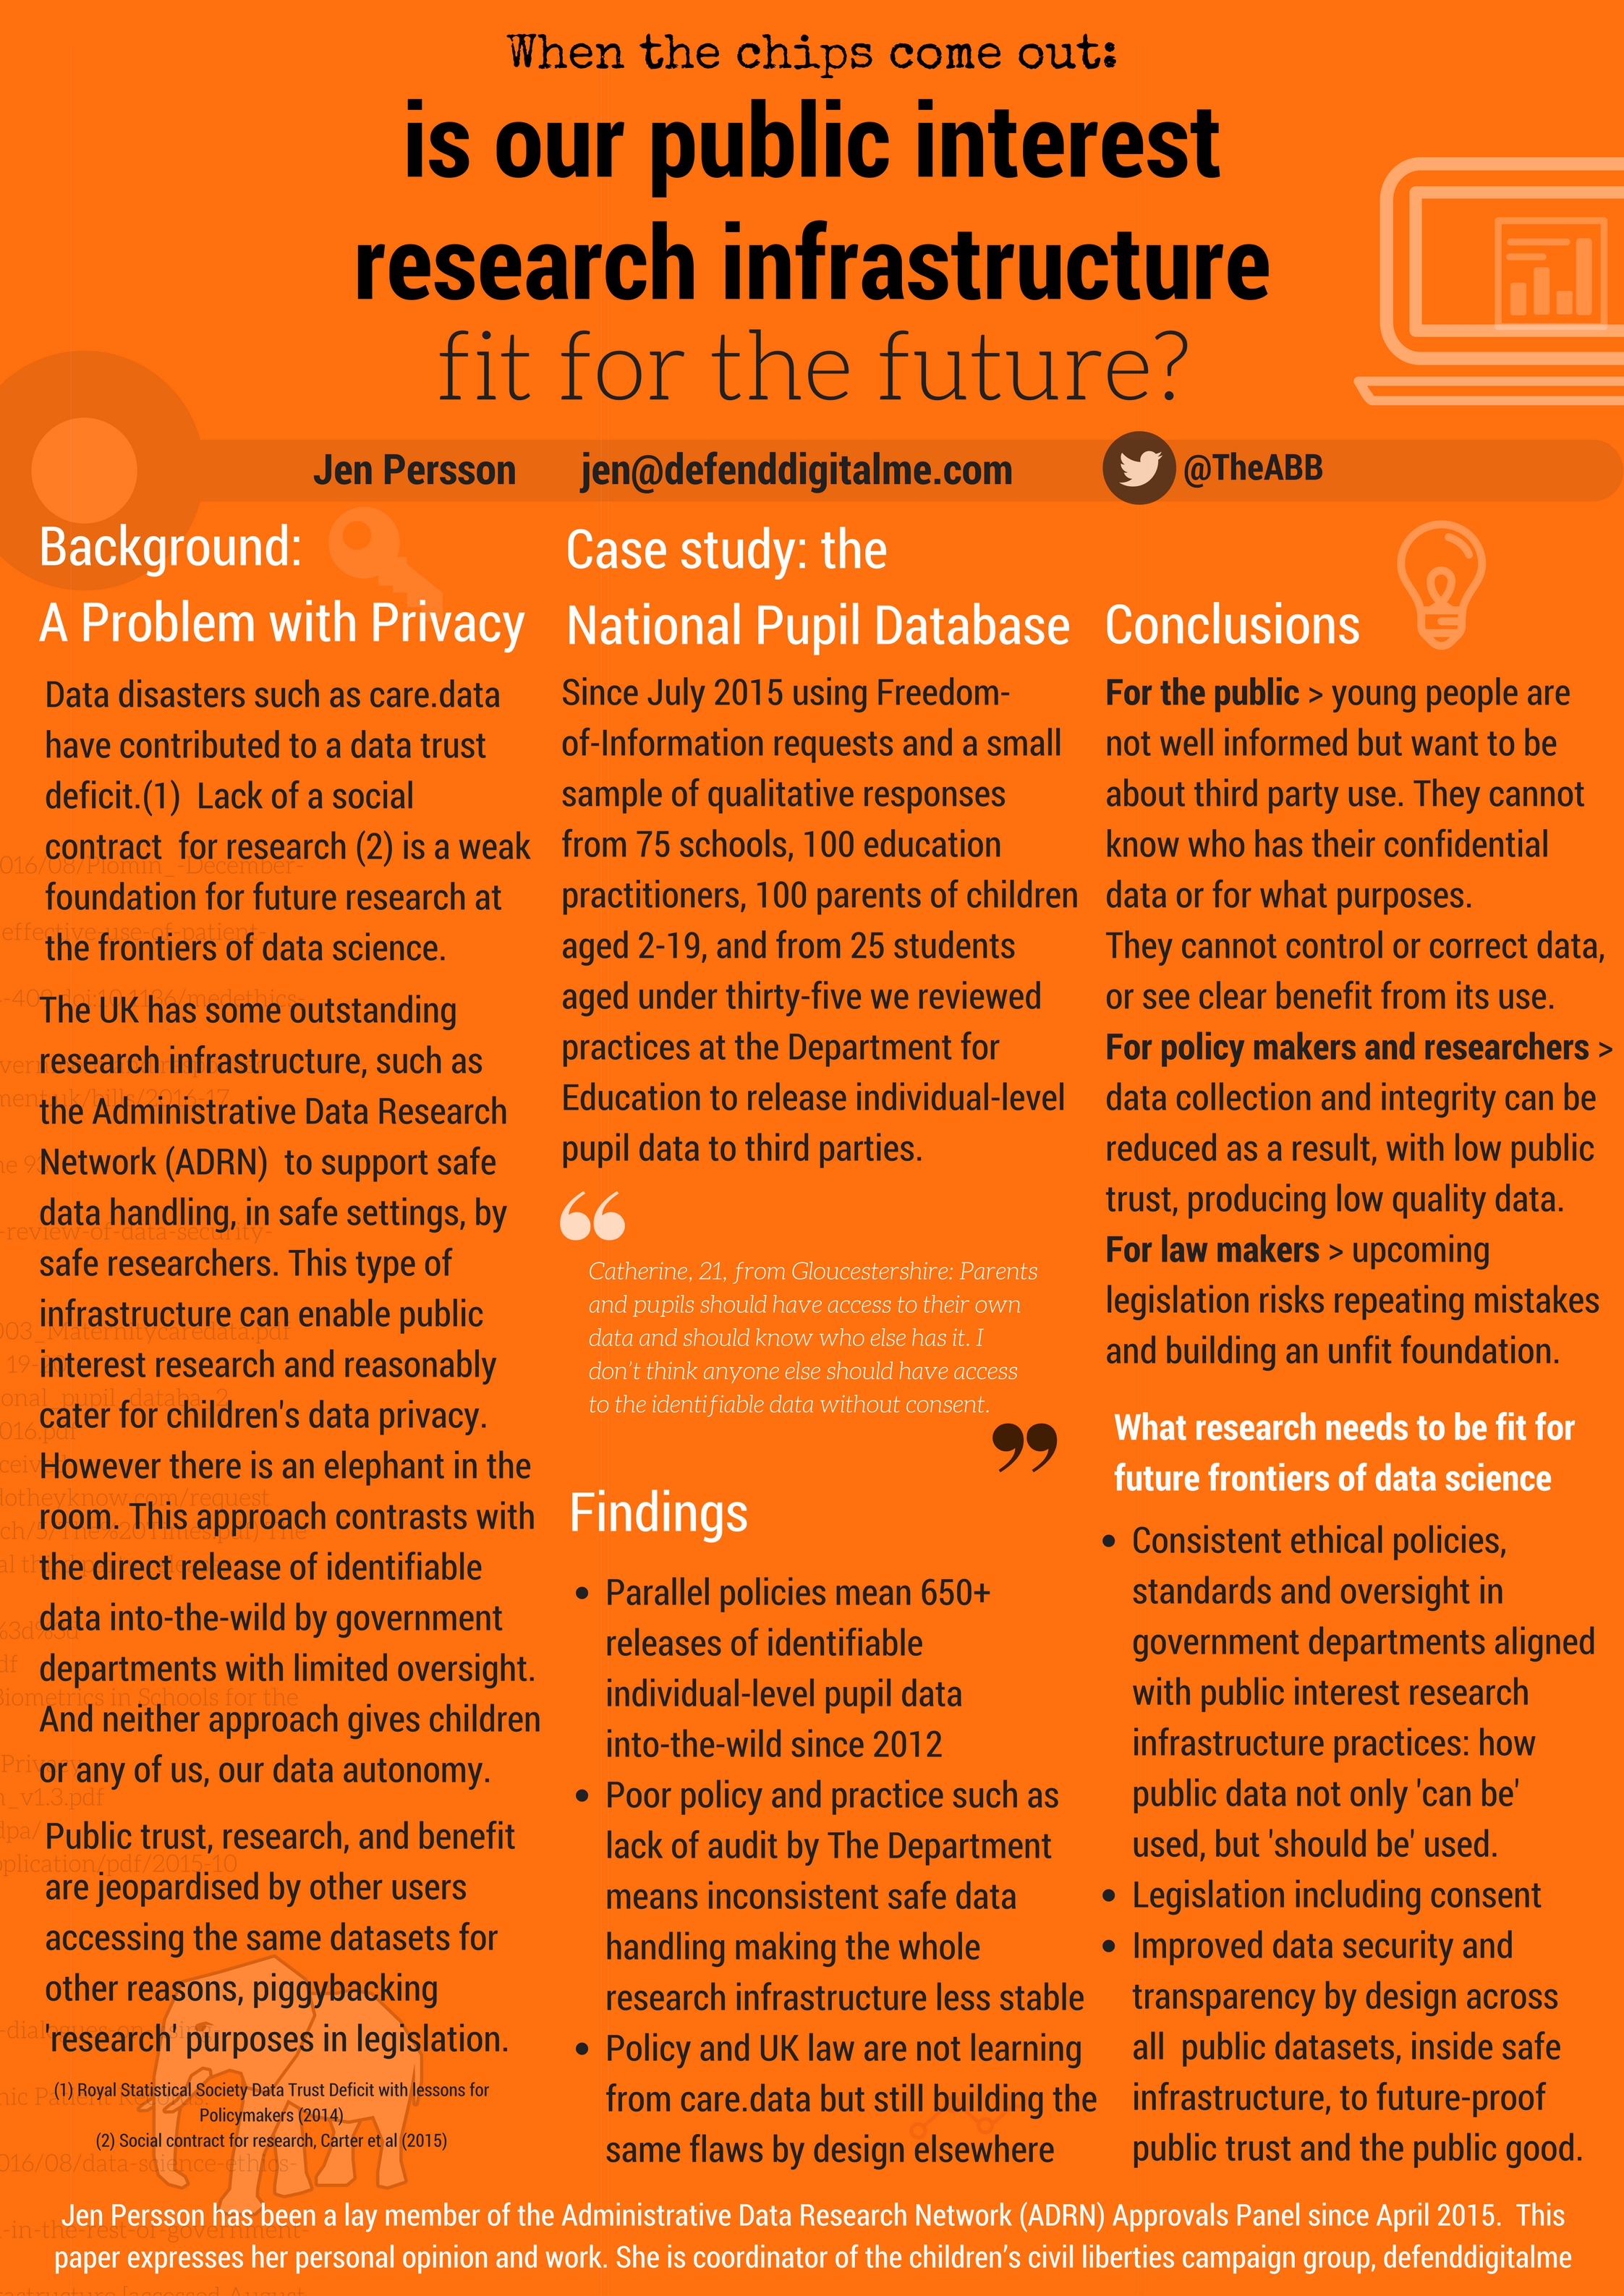
Highlighting the policy and practice failings in the niche area of the National Pupil Database serves only to get ideas from others how  policy and practice could be better. 20 million school children’s records is not a bad place to start to make data practice better.

The questions that seem hardest to move forward are the simplest: how to involve everyone in what data and policy may bring for future and not leave out certain communities through carelessness.

If the public is not encouraged to understand how our own personal data are collected and used, how can we expect to grow great data scientists of the future? What uses of data put good uses at risk?

And we must make sure we don’t miss other things, while data takes up the time and focus of today’s policy makers and great minds alike.
cb-poster-for-web

Mum, are we there yet? Why should AI care.

Mike Loukides drew similarities between the current status of AI and children’s learning in an article I read this week.

The children I know are always curious to know where they are going, how long will it take, and how they will know when they get there. They ask others for guidance often.

Loukides wrote that if you look carefully at how humans learn, you see surprisingly little unsupervised learning.

If unsupervised learning is a prerequisite for general intelligence, but not the substance, what should we be looking for, he asked. It made me wonder is it also true that general intelligence is a prerequisite for unsupervised learning? And if so, what level of learning must AI achieve before it is capable of recursive self-improvement? What is AI being encouraged to look for as it learns, what is it learning as it looks?

What is AI looking for and how will it know when it gets there?

Loukides says he can imagine a toddler learning some rudiments of counting and addition on his or her own, but can’t imagine a child developing any sort of higher mathematics without a teacher.

I suggest a different starting point. I think children develop on their own, given a foundation. And if the foundation is accompanied by a purpose — to understand why they should learn to count, and why they should want to — and if they have the inspiration, incentive and  assets they’ll soon go off on their own, and outstrip your level of knowledge. That may or may not be with a teacher depending on what is available, cost, and how far they get compared with what they want to achieve.

It’s hard to learn something from scratch by yourself if you have no boundaries to set knowledge within and search for more, or to know when to stop when you have found it.

You’ve only to start an online course, get stuck, and try to find the solution through a search engine to know how hard it can be to find the answer if you don’t know what you’re looking for. You can’t type in search terms if you don’t know the right words to describe the problem.

I described this recently to a fellow codebar-goer, more experienced than me, and she pointed out something much better to me. Don’t search for the solution or describe what you’re trying to do, ask the search engine to find others with the same error message.

In effect she said, your search is wrong. Google knows the answer, but can’t tell you what you want to know, if you don’t ask it in the way it expects.

So what will AI expect from people and will it care if we dont know how to interrelate? How does AI best serve humankind and defined by whose point-of-view? Will AI serve only those who think most closely in AI style steps and language?  How will it serve those who don’t know how to talk about, or with it? AI won’t care if we don’t.

If as Loukides says, we humans are good at learning something and then applying that knowledge in a completely different area, it’s worth us thinking about how we are transferring our knowledge today to AI and how it learns from that. Not only what does AI learn in content and context, but what does it learn about learning?

His comparison of a toddler learning from parents — who in effect are ‘tagging’ objects through repetition of words while looking at images in a picture book — made me wonder how we will teach AI the benefit of learning? What incentive will it have to progress?

“the biggest project facing AI isn’t making the learning process faster and more efficient. It’s moving from machines that solve one problem very well (such as playing Go or generating imitation Rembrandts) to machines that are flexible and can solve many unrelated problems well, even problems they’ve never seen before.”

Is the skill to enable “transfer learning” what will matter most?

For AI to become truly useful, we need better as a global society to understand *where* it might best interface with our daily lives, and most importantly *why*.  And consider *who* is teaching and AI and who is being left out in the crowdsourcing of AI’s teaching.

Who is teaching AI what it needs to know?

The natural user interfaces for people to interact with today’s more common virtual assistants (Amazon’s Alexa, Apple’s Siri and Viv, Microsoft  and Cortana) are not just providing information to the user, but through its use, those systems are learning. I wonder what percentage of today’s  population is using these assistants, how representative are they, and what our AI assistants are being taught through their use? Tay was a swift lesson learned for Microsoft.

In helping shape what AI learns, what range of language it will use to develop its reference words and knowledge, society co-shapes what AI’s purpose will be —  and for AI providers to know what’s the point of selling it. So will this technology serve everyone?

Are providers counter-balancing what AI is currently learning from crowdsourcing, if the crowd is not representative of society?

So far we can only teach machines to make decisions based on what we already know, and what we can tell it to decide quickly against pre-known references using lots of data. Will your next image captcha, teach AI to separate the sloth from the pain-au-chocolat?

One of the task items for machine processing is better searches. Measurable goal driven tasks have boundaries, but who sets them? When does a computer know, if it’s found enough to make a decision. If the balance of material about the Holocaust on the web for example, were written by Holocaust deniers will AI know who is right? How will AI know what is trusted and by whose measure?

What will matter most is surely not going to be how to optimise knowledge transfer from human to AI — that is the baseline knowledge of supervised learning — and it won’t even be for AI to know when to use its skill set in one place and when to apply it elsewhere in a different context; so-called learning transfer, as Mike Loukides says. But rather, will AI reach the point where it cares?

  • Will AI ever care what it should know and where to stop or when it knows enough on any given subject?
  • How will it know or care if what it learns is true?
  • If in the best interests of advancing technology or through inaction  we do not limit its boundaries, what oversight is there of its implications?

Online limits will limit what we can reach in Thinking and Learning

If you look carefully at how humans learn online, I think rather than seeing  surprisingly little unsupervised learning, you see a lot of unsupervised questioning. It is often in the questioning that is done in private we discover, and through discovery we learn. Often valuable discoveries are made; whether in science, in maths, or important truths are found where there is a need to challenge the status quo. Imagine if Galileo had given up.

The freedom to think freely and to challenge authority, is vital to protect, and one reason why I and others are concerned about the compulsory web monitoring starting on September 5th in all schools in England, and its potential chilling effect. Some are concerned who  might have access to these monitoring results today or in future, if stored could they be opened to employers or academic institutions?

If you tell children do not use these search terms and do not be curious about *this* subject without repercussions, it is censorship. I find the idea bad enough for children, but for us as adults its scary.

As Frankie Boyle wrote last November, we need to consider what our internet history is:

“The legislation seems to view it as a list of actions, but it’s not. It’s a document that shows what we’re thinking about.”

Children think and act in ways that they may not as an adult. People also think and act differently in private and in public. It’s concerning that our private online activity will become visible to the State in the IP Bill — whether photographs that captured momentary actions in social media platforms without the possibility to erase them, or trails of transitive thinking via our web history — and third-parties may make covert judgements and conclusions about us, correctly or not, behind the scenes without transparency, oversight or recourse.

Children worry about lack of recourse and repercussions. So do I. Things done in passing, can take on a permanence they never had before and were never intended. If expert providers of the tech world such as Apple Inc, Facebook Inc, Google Inc, Microsoft Corp, Twitter Inc and Yahoo Inc are calling for change, why is the government not listening? This is more than very concerning, it will have disastrous implications for trust in the State, data use by others, self-censorship, and fear that it will lead to outright censorship of adults online too.

By narrowing our parameters what will we not discover? Not debate?  Or not invent? Happy are the clockmakers, and kids who create. Any restriction on freedom to access information, to challenge and question will restrict children’s learning or even their wanting to.  It will limit how we can improve our shared knowledge and improve our society as a result. The same is true of adults.

So in teaching AI how to learn, I wonder how the limitations that humans put on its scope — otherwise how would it learn what the developers want — combined with showing it ‘our thinking’ through search terms,  and how limitations on that if users self-censor due to surveillance, will shape what AI will help us with in future and will it be the things that could help the most people, the poorest people, or will it be people like those who programme the AI and use search terms and languages it already understands?

Who is accountable for the scope of what we allow AI to do or not? Who is accountable for what AI learns about us, from our behaviour data if it is used without our knowledge?

How far does AI have to go?

The leap for AI will be if and when AI can determine what it doesn’t know, and it sees a need to fill that gap. To do that, AI will need to discover a purpose for its own learning, indeed for its own being, and be able to do so without limitation from the that humans shaped its framework for doing so. How will AI know what it needs to know and why? How will it know, what it knows is right and sources to trust? Against what boundaries will AI decide what it should engage with in its learning, who from and why? Will it care? Why will it care? Will it find meaning in its reason for being? Why am I here?

We assume AI will know better. We need to care, if AI is going to.

How far are we away from a machine that is capable of recursive self-improvement, asks John Naughton in yesterday’s Guardian, referencing work by Yuval Harari suggesting artificial intelligence and genetic enhancements will usher in a world of inequality and powerful elites. As I was finishing this, I read his article, and found myself nodding, as I read the implications of new technology focus too much on technology and too little on society’s role in shaping it.

AI at the moment has a very broad meaning to the general public. Is it living with life-supporting humanoids?  Do we consider assistive search tools as AI? There is a fairly general understanding of “What is A.I., really?” Some wonder if we are “probably one of the last generations of Homo sapiens,” as we know it.

If the purpose of AI is to improve human lives, who defines improvement and who will that improvement serve? Is there a consensus on the direction AI should and should not take, and how far it should go? What will the global language be to speak AI?

As AI learning progresses, every time AI turns to ask its creators, “Are we there yet?”,  how will we know what to say?

image: Stephen Barling flickr.com/photos/cripsyduck (CC BY-NC 2.0)